How Bloom Filters Work: Bit Arrays, Hash Functions and False Positives
The tiny probabilistic data structure that lets databases, CDNs and browsers skip work they don't need to do
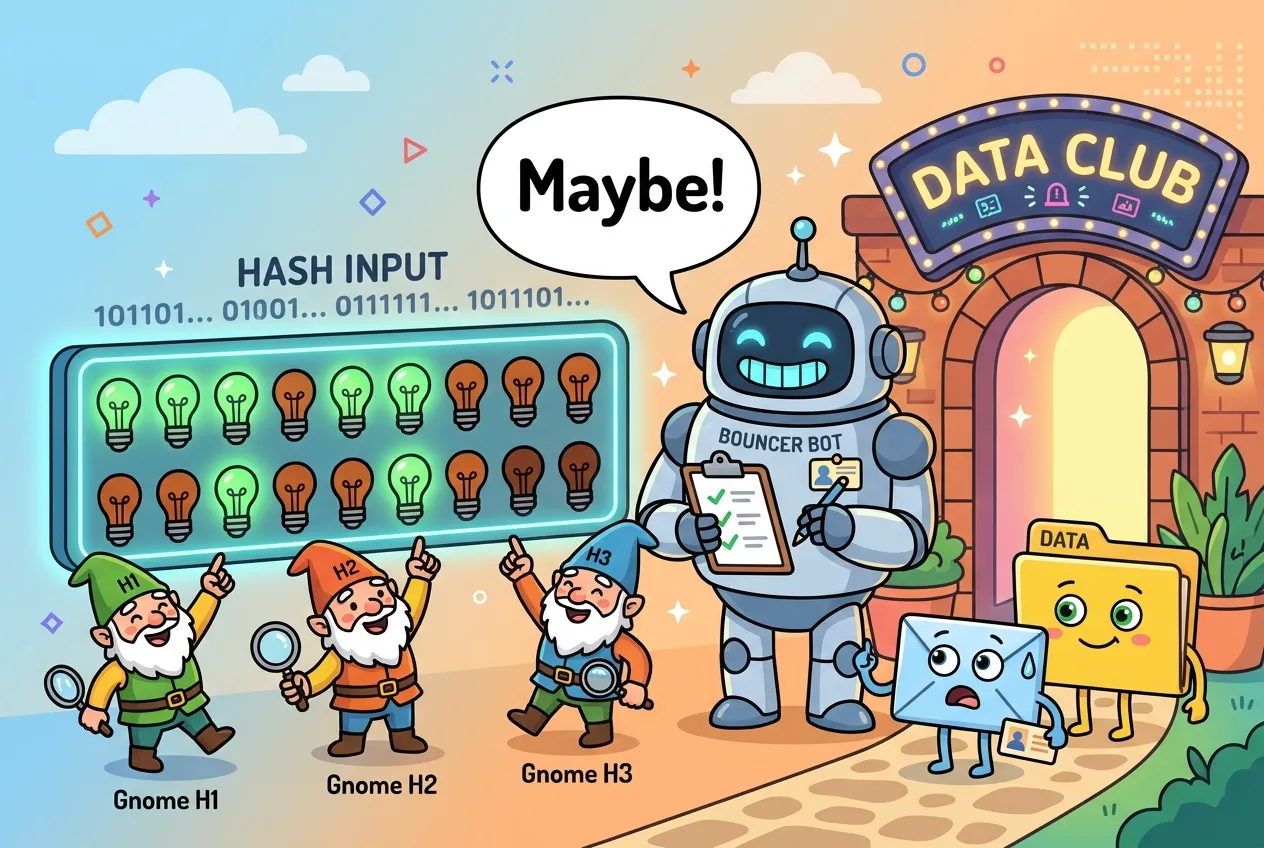
What if a data structure could tell you "definitely not here" in a few nanoseconds, using about a byte per item, no matter how long the items are? That is the quiet trick behind a lot of fast software.
This guide explains how Bloom filters work: the bit array, the hash functions, why they sometimes say "maybe" when the answer is no, how to size one, and where databases, CDNs and browsers put them to work.
The problem: asking "is it in the set?" cheaply
Plenty of systems spend most of their time checking for things that aren't there. A database looks for a row key in files that don't contain it. A cache checks whether it has seen a URL before. A sign-up form wants to know whether a username is taken.
A hash set answers exactly, but it has to store every item. With millions of long strings, that gets expensive. In 1970, Burton Bloom proposed accepting a small, controlled error in exchange for a big memory saving. His example was a hyphenation dictionary where most words follow simple rules and only a minority need a slow disk lookup.
How a Bloom filter works
A Bloom filter is just two ingredients:
- An array of m bits, all starting at 0.
- k hash functions, each mapping an item to one position in that array.
Adding an item
Run the item through all k hash functions and set each of the k resulting bits to 1. The item itself is never stored.
Checking an item
Hash it the same way and look at the same k bits:
- If any of them is 0, the item was definitely never added. Adding it would have set that bit.
- If all of them are 1, the item is probably in the set. Other items may have set those bits by coincidence.
That second case is a false positive. The reverse error, a false negative, can't happen in a standard Bloom filter. This one-sided guarantee is what makes the structure useful: you only pay for the expensive real lookup when the filter says "maybe."
Sizing a Bloom filter: the false-positive math
Three numbers trade against each other: n (items you expect), m (bits), and p (the false-positive rate you can tolerate). Too few hash functions and each item leaves a faint fingerprint; too many and the array fills with 1s. The sweet spot is reached when about half the bits are set.
With n and p chosen, the standard formulas are:
m = -n · ln(p) / (ln 2)²      # bits needed
k = (m / n) · ln 2 # hash functionsRedis documents what that works out to in practice:
| Target false-positive rate | Bits per item | Hash functions |
|---|---|---|
| 1% (1 in 100) | 9.585 | 7 |
| 0.1% (1 in 1,000) | 14.378 | 10 |
| 0.01% (1 in 10,000) | 19.170 | 14 |
Each tenfold improvement costs only about 4.8 extra bits per item. A million email addresses at a 1% error rate fit in roughly 1.2 MB, whether the addresses are 10 characters or 100.
A working Bloom filter in Python
You don't need k unrelated hash functions. A well-known shortcut from Kirsch and Mitzenmacher, called double hashing, derives all k positions from two base hashes with negligible loss in accuracy. Here it is with one SHA-256 digest split in two:
import hashlib, math

class BloomFilter:
    def __init__(self, capacity, error_rate=0.01):
        self.m = math.ceil(-capacity * math.log(error_rate) / math.log(2) ** 2)
        self.k = max(1, round(self.m / capacity * math.log(2)))
        self.bits = bytearray((self.m + 7) // 8)

    def _positions(self, item):
        digest = hashlib.sha256(item.encode()).digest()
        h1 = int.from_bytes(digest[:8], "big")
        h2 = int.from_bytes(digest[8:16], "big") | 1
        return [(h1 + i * h2) % self.m for i in range(self.k)]

    def add(self, item):
        for p in self._positions(item):
            self.bits[p // 8] |= 1 << (p % 8)

    def might_contain(self, item):
        return all(self.bits[p // 8] & (1 << (p % 8))
                   for p in self._positions(item))

bf = BloomFilter(capacity=1_000_000, error_rate=0.01)
bf.add("alice@example.com")
print(bf.might_contain("alice@example.com"))  # True
print(bf.might_contain("bob@example.com")) # False (almost always)In production you'd pick a faster non-cryptographic hash such as MurmurHash or xxHash. Cryptographic hashes are built for a different job, as our guide to how password hashing works explains.
Where Bloom filters are used
- Databases. Apache Cassandra keeps a Bloom filter per SSTable so reads can skip files that can't hold the requested partition. Bigtable, HBase and ScyllaDB use the same idea, and PostgreSQL ships a
bloomindex extension. It's the same "avoid the disk" goal behind how B-tree database indexes work. - CDN caches. Akamai found that nearly three-quarters of objects were requested only once. By caching an object only on its second request, tracked with a Bloom filter, it kept these "one-hit wonders" off disk. More on caches in how HTTP caching works.
- Browsers. Chrome once screened URLs against a local Bloom filter before doing a full Safe Browsing check. Firefox's CRLite uses cascading Bloom filters to ship certificate revocations to browsers.
- Recommendations. Medium has used them to avoid recommending stories a reader has already seen.
Tuning one in the real world
Cassandra exposes the trade-off directly as bloom_filter_fp_chance. Its default is 0.01 for most tables and 0.1 for tables using leveled compaction, and its docs note that 0.01 needs about three times the memory of 0.1. Changing it affects only newly written files until they are compacted:
ALTER TABLE shop.orders WITH bloom_filter_fp_chance = 0.01;Redis does the sizing for you. BF.RESERVE key 0.001 1000000 creates a filter for a million items at 0.1%. When capacity is exceeded, Redis adds a sub-filter rather than letting the error rate drift, unless you pass NONSCALING, in which case adds fail once it's full.
Bloom filter alternatives
| Structure | Deletes? | Best for |
|---|---|---|
| Bloom filter | No | Simple, fast, append-only sets |
| Counting Bloom filter | Yes | Deletes needed; costs 3–4× the memory |
| Cuckoo filter | Yes | Deletes plus better memory locality |
| Xor filter | No (static) | Sets built once, queried many times |
Key takeaways
- A Bloom filter is a bit array plus k hash functions that answers "definitely not" or "probably yes."
- False positives are possible; false negatives are not, so a "no" lets you skip expensive work safely.
- Memory depends on the error rate, not item size: about 9.6 bits per item for 1%.
- Size it with m = −n·ln(p)/(ln 2)² and k = (m/n)·ln 2, and don't overfill it.
- Standard Bloom filters can't delete; use counting or cuckoo filters when you need to.
Frequently asked questions
Can a Bloom filter return a false negative?
Not a standard one. If an item was added, all of its bits were set to 1 and nothing in the basic design clears them, so the filter will always report it as possibly present.
What happens if I add more items than planned?
Nothing breaks, but more bits flip to 1 and the false-positive rate climbs steadily. Rebuild the filter larger, or use a scalable version like Redis's default, which adds sub-filters as it grows.
Can I list the items stored in a Bloom filter?
No. It stores only bits, not the items, so you can test membership but never enumerate or recover the contents. Keep the real data elsewhere.
Can two Bloom filters be merged?
Yes, if they have the same size and hash functions. A bitwise OR of the two arrays gives exactly the filter you would get by adding both sets to one filter.
Comments
No comments yet — be the first to share your thoughts.
Join the discussion