How Database Indexes Work: B-Trees, Lookups and the Hidden Cost of Speed
Why one line of SQL can turn an eight-second query into milliseconds, and what it costs you
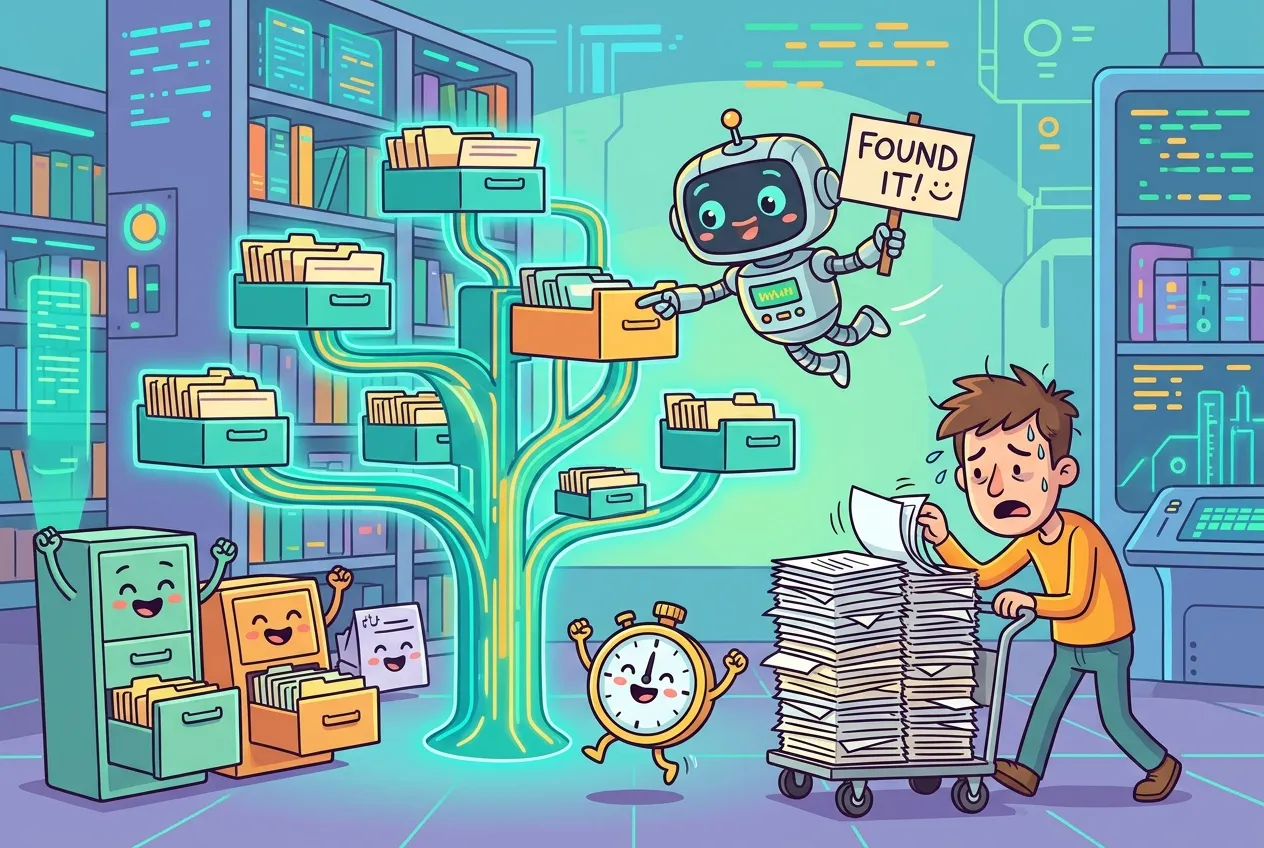
A query that took a few milliseconds last spring now takes eight seconds. Nothing in the code changed. The table just grew. Nine times out of ten, the fix is one line of SQL that creates an index.
Indexes are the single biggest lever most developers have over database speed, yet they're often treated as magic. This guide explains how database indexes work: what an index actually stores, why lookups get dramatically faster, how multi-column and covering indexes behave, and what every index costs you on writes. The examples use PostgreSQL, MySQL and SQLite, but the ideas apply almost everywhere.
The problem: the full table scan
Picture a customers table with ten million rows and this query:
SELECT name, email FROM customers WHERE email = 'ana@example.com';Without help, the database has only one option: read every row and check whether its email matches. SQLite's documentation calls this a full table scan, and its cost grows in direct proportion to the number of rows. Double the table, double the work. For a small table that's fine. For a big one, it's the eight-second query.
The trick that avoids it is the same one a phone book uses: keep things sorted. If rows are in order, you can jump to the middle, decide which half holds your answer, and repeat. That's a binary search, and it needs roughly log N steps instead of N. SQLite's query-planner guide estimates that for a table of ten million rows, searching this way is on the order of a million times faster than scanning.
What a database index actually stores
A table can only be physically sorted one way, so an index is a separate sorted structure. SQLite describes it plainly: an index holds copies of the indexed column values, in order, each paired with a pointer back to the full row (in SQLite, the rowid). Looking up a value becomes two steps:
- Search the index to find the matching entry and its row pointer.
- Follow the pointer to fetch the rest of the row from the table.
For K matching rows out of N, SQLite puts the cost at about (K+1) × log N. When K is small, that's tiny compared with reading all N rows.
Why it's usually a B-tree
Real databases don't keep indexes as one long sorted list, because inserting into the middle of a list is slow. Instead they use a B-tree: a shallow, balanced tree of fixed-size pages where each page holds many sorted keys and pointers to the pages below. A lookup walks from the root down to a leaf in a handful of page reads, and the tree rebalances itself as data changes. B-tree is the default index type in PostgreSQL, and it handles equality and range comparisons (=, <, >, BETWEEN, IN) as well as IS NULL checks.
Clustered vs. secondary indexes
Some engines go a step further and store the table itself inside an index. In MySQL's InnoDB, every table has a clustered index that holds the row data, normally the primary key. If you don't define one, InnoDB uses the first unique index whose columns are all NOT NULL, and failing that, it creates a hidden index on a generated row ID.
Every other index is a secondary index, and each of its entries stores the row's primary key value. Fetching a full row through a secondary index means a second search through the clustered index. That's why the MySQL manual recommends a short primary key: a long one makes every secondary index bigger.
Creating an index and checking it works
Creating an index is one statement. Confirming the database actually uses it is the step people skip.
-- PostgreSQL / MySQL / SQLite
CREATE INDEX idx_customers_email ON customers (email);

-- PostgreSQL: see the plan the database picks
EXPLAIN SELECT name, email FROM customers
WHERE email = 'ana@example.com';

-- SQLite equivalent
EXPLAIN QUERY PLAN SELECT name, email FROM customers
WHERE email = 'ana@example.com';The database decides on its own whether to use an index. PostgreSQL's documentation notes that the planner only picks one when it judges it cheaper than a sequential scan, and that you may need to run ANALYZE regularly so the planner has fresh statistics to judge with.
Multi-column and covering indexes
Column order matters
An index can span several columns, such as (last_name, first_name). Entries are sorted by the first column, and each later column only breaks ties. The practical rule from SQLite's guide is that the index helps when your query constrains the left-most columns. A search on last_name alone can use it; a search on first_name alone generally can't, just as a phone book sorted by surname won't help you find everyone named Maria.
A useful corollary: if one index's columns are a prefix of another's, the shorter one is redundant. An index on (last_name) adds nothing when (last_name, first_name) already exists.
Covering indexes skip the table entirely
If an index contains every column a query needs, both what it filters on and what it returns, the database can answer from the index alone and never touch the table. SQLite calls this a covering index and says it roughly halves the number of searches. In the example above, an index on (email, name) would cover the query.
Beyond B-trees: other index types
B-trees cover most needs, but PostgreSQL ships several specialized types for data that doesn't sort neatly:
| Type | Best for | Limitation |
|---|---|---|
| B-tree (default) | Equality, ranges, sorting, prefix LIKE 'abc%' | Not suited to "contains" searches |
| Hash | Simple equality lookups | Only supports =; no ranges |
| GIN | Multi-valued data like arrays; tests whether values are present | Built for "contains"-style operators |
| GiST / SP-GiST | Geometric data and nearest-neighbor searches | Behavior depends on the operator class |
| BRIN | Very large tables where values track physical order, such as timestamps in a log | Only effective when that correlation exists |
BRIN is a neat example of trading precision for size: rather than indexing every row, it stores only the minimum and maximum values for each range of table blocks, which keeps it very small.
The cost: indexes aren't free
Every index is a copy of data that must stay in sync. PostgreSQL's documentation is direct about the overhead: each insert, update and delete has to maintain every index on the table, and indexes that are rarely or never used should be removed. A practical checklist:
- Index for real queries. Start from slow queries and the columns in their
WHERE,JOINandORDER BYclauses, not from a guess. - Prefer one good composite index over several overlapping single-column ones.
- Keep primary keys short on InnoDB, since they're copied into every secondary index.
- Audit unused indexes periodically; they slow writes and use storage for nothing.
- Verify with EXPLAIN after every change, and refresh statistics if the planner ignores a sensible index.
If you enjoy seeing how familiar tools work internally, the same "sorted keys plus pointers" thinking shows up in how Git stores commits under the hood.
Key takeaways
- Without an index, a query scans every row; with one, it searches a sorted structure in roughly log N steps.
- Most indexes are B-trees that store sorted column values plus pointers back to rows.
- In multi-column indexes, the left-most columns decide whether the index can be used.
- Covering indexes answer queries without touching the table at all.
- Every index slows writes, so add them for real queries, confirm with EXPLAIN, and drop the ones nobody uses.
Frequently asked questions
Should I index every column I filter on?
No. Each index adds work to every insert, update and delete. Index the columns used by frequent or slow queries, and prefer a well-ordered composite index over many single-column ones.
Why isn't the database using my index?
The planner may estimate that a scan is cheaper, for example when a query matches a large share of the table, or its statistics may be stale. Check the plan with EXPLAIN and refresh statistics with ANALYZE.
Does a primary key create an index automatically?
In the major engines, yes. In MySQL's InnoDB, the primary key becomes the clustered index that physically holds the row data.
What is a covering index?
An index that contains every column a query needs, so the database can return results from the index alone without reading the underlying table.
Comments
No comments yet — be the first to share your thoughts.
Join the discussion