How API Rate Limiting Works: Token Bucket, Sliding Windows and 429s
The counting tricks that keep APIs fair, fast and online, and how clients should respond when they hear "slow down"
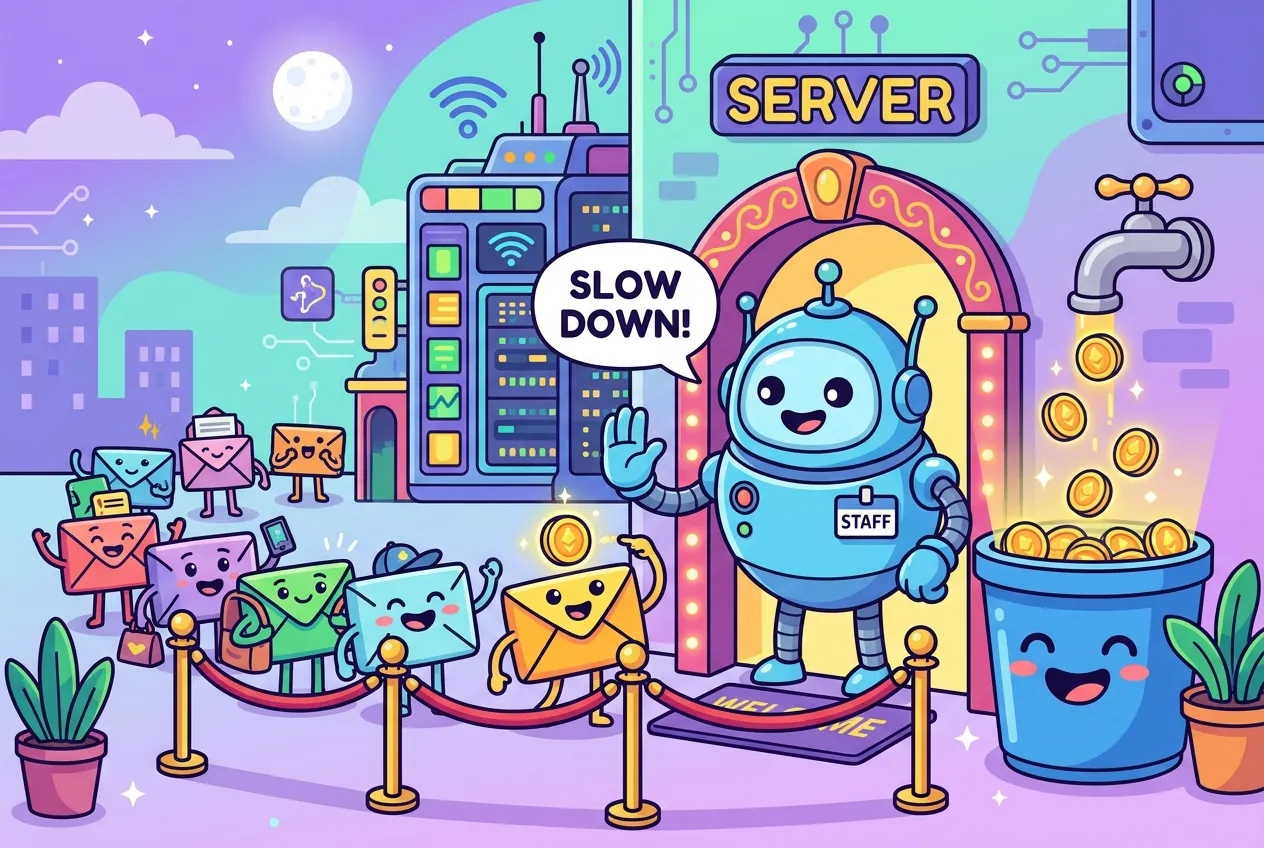
Every public API has a bouncer at the door. Send a few requests and you are waved through; send a few thousand in a second and you get a polite but firm 429 Too Many Requests. That bouncer is a rate limiter, and the way it counts decides whether your users feel a smooth service or a wall.
This guide explains how API rate limiting works: why services limit traffic at all, the four algorithms almost every limiter is built on, how servers tell clients to slow down, and how to build a client that backs off gracefully instead of hammering a service that is already saying no.
Why APIs limit requests
A rate limiter caps how many requests a client can make in a period of time. MDN describes the 429 status as the server's way of asking a client to slow down, with limits usually keyed by IP address or, for authenticated traffic, by user or application. The reasons are practical:
- Fairness. One noisy customer should not degrade the service for everyone else.
- Protection. Limits blunt credential stuffing, scraping and accidental retry storms from a buggy script.
- Cost control. Every request costs compute, database time and bandwidth, and some (like AI model calls) are expensive.
- Stability. Shedding excess load early keeps the system answering the requests it can handle.
Stripe's engineering blog describes running four separate limiters in production: a per-user request rate limiter, a limit on concurrent in-flight requests, and two load shedders that protect critical traffic when the fleet is under strain. Its advice is to start with the simple per-user request limit, because that one catches the most problems.
How API rate limiting works: the four core algorithms
Under the branding, nearly every limiter uses one of four counting strategies. Each makes a different trade-off between accuracy, memory and how it treats bursts.
1. Fixed window counter
Split time into windows, such as each calendar minute, and keep one counter per client per window. Reject once the counter passes the limit; reset when the window rolls over. It is cheap and easy to explain, but it has an edge problem: a client can send a full quota at 12:00:59 and another full quota at 12:01:00, briefly doubling the intended rate.
2. Sliding window log
Store a timestamp for every request and count how many fall in the last N seconds. This is perfectly accurate and has no edge problem, but memory grows with traffic, because you keep one entry per request.
3. Sliding window counter
A popular middle ground. Keep the fixed-window counters, but estimate the rolling count by weighting the previous window by how much of it still overlaps the last N seconds. If you are 25% of the way into the current minute, the estimate is the current count plus 75% of the previous minute's count. It assumes traffic was spread evenly, so it is approximate, but it smooths the edge spike using just two numbers per client.
4. Token bucket and leaky bucket
Imagine a bucket that holds up to B tokens and refills at R tokens per second. Each request spends a token; when the bucket is empty, requests are rejected. A full bucket lets a client burst up to B requests at once, while the long-run average can never exceed R. That combination of "bursty but bounded" is why the token bucket is so widely used for APIs.
The leaky bucket is its mirror image: requests pour into a queue that drains at a fixed rate, smoothing output into an even stream. NGINX's limit_req module documents that it uses the leaky bucket method.
import time

class TokenBucket:
    def __init__(self, rate, capacity):
        self.rate = rate          # tokens added per second
        self.capacity = capacity  # maximum burst size
        self.tokens = capacity
        self.updated = time.monotonic()

    def allow(self, cost=1):
        now = time.monotonic()
        # Refill lazily based on time elapsed since the last call
        elapsed = now - self.updated
        self.tokens = min(self.capacity, self.tokens + elapsed * self.rate)
        self.updated = now
        if self.tokens >= cost:
            self.tokens -= cost
            return True
        return False

bucket = TokenBucket(rate=5, capacity=10)  # 5 req/s, bursts of 10
print(bucket.allow()) # True| Algorithm | Memory per client | Allows bursts? | Main weakness |
|---|---|---|---|
| Fixed window | One counter | Yes, up to 2x at window edges | Boundary spikes |
| Sliding window log | One timestamp per request | No | Memory grows with traffic |
| Sliding window counter | Two counters | Slightly | Approximate |
| Token bucket | Count and timestamp | Yes, up to bucket size | Two knobs to tune |
| Leaky bucket | Queue or counter | Queued, then smoothed | Adds latency when queuing |
Telling clients to slow down
The 429 status and Retry-After
The 429 status code was defined in RFC 6585 in 2012. A server may attach a Retry-After header saying how long to wait, either as a number of seconds or an HTTP date:
HTTP/1.1 429 Too Many Requests
Content-Type: application/json
Retry-After: 30

{"error": "rate_limited", "message": "Try again in 30 seconds."}
Like other responses, 429s interact with HTTP caching rules, so it is worth sending Cache-Control: no-store on rejection responses to keep a CDN from replaying them to other users.
The emerging RateLimit headers
For years, APIs invented their own X-RateLimit-* headers with slightly different meanings. The IETF HTTPAPI working group is standardizing a replacement. Its Internet-Draft (version 11, May 2026, still a work in progress) defines two fields: RateLimit-Policy to describe quotas, and RateLimit to report what is left right now.
RateLimit-Policy: "burst";q=100;w=60, "daily";q=1000;w=86400
RateLimit: "burst";r=42;t=18
Here q is the quota, w the window in seconds, r the remaining quota and t the seconds until it resets. The draft says that when both are present, Retry-After takes precedence, and that a positive remaining count is a hint, not a promise.
Rate limiting in practice
At the edge with NGINX
A reverse proxy is often the easiest place to start. This configuration allows each IP about 10 requests per second, absorbs short bursts of 20 without delay, and returns a proper 429:
limit_req_zone $binary_remote_addr zone=api:10m rate=10r/s;

server {
    location /api/ {
        limit_req zone=api burst=20 nodelay;
        limit_req_status 429;
    }
}
Per the NGINX docs, burst sets how many excess requests can queue, and nodelay serves those queued requests immediately rather than spacing them out.
Across many servers
With several app servers, each one counting alone would multiply your real limit. Teams usually move counters into a shared, fast store such as Redis and update them atomically, so that the check and the increment happen as one step. Choose the key carefully: per API key or user is fairer than per IP, since many people can share one address behind an office or mobile network. If your API uses OAuth 2.0 access tokens, the client ID makes a natural key.
Being a good client
- Honor
Retry-Afterexactly when it is present. - Back off exponentially with jitter when it is not: wait 1s, 2s, 4s and so on, plus a random amount so thousands of clients do not retry in lockstep.
- Cap your retries and surface a clear error instead of looping forever.
- Read the remaining-quota headers and slow down before you hit zero.
- Batch and cache so you need fewer calls in the first place.
Key takeaways
- Rate limits protect fairness, stability and cost by capping requests per client over time.
- Fixed windows are simple but spike at boundaries; sliding windows fix that at some cost.
- The token bucket allows short bursts while enforcing a steady long-run rate, which suits most APIs.
- Reject with
429plusRetry-After, and watch the IETFRateLimitheaders as they mature. - Clients should honor Retry-After and use exponential backoff with jitter.
Frequently asked questions
What is the difference between rate limiting and throttling?
The terms are often used interchangeably. When they are distinguished, rate limiting usually means rejecting requests over a limit, while throttling means slowing or queuing them, as a leaky bucket does.
Which rate limiting algorithm should I use?
For most APIs, a token bucket is a strong default because it allows short bursts while capping the average rate. Use a sliding window counter if you want simple per-minute quotas without boundary spikes.
Should I rate limit by IP address or by API key?
Prefer an API key, user or client ID when requests are authenticated, because many users can share one IP. Use IP limits for anonymous endpoints such as login and sign-up pages.
What should a client do after receiving a 429?
Wait for the time given in the Retry-After header if there is one. Otherwise retry with exponential backoff plus random jitter, and stop after a few attempts.
Comments
No comments yet — be the first to share your thoughts.
Join the discussion