How Load Balancers Work: Layer 4 vs Layer 7, Algorithms and Health Checks
The traffic cop behind every busy website, and how it decides which server answers your request
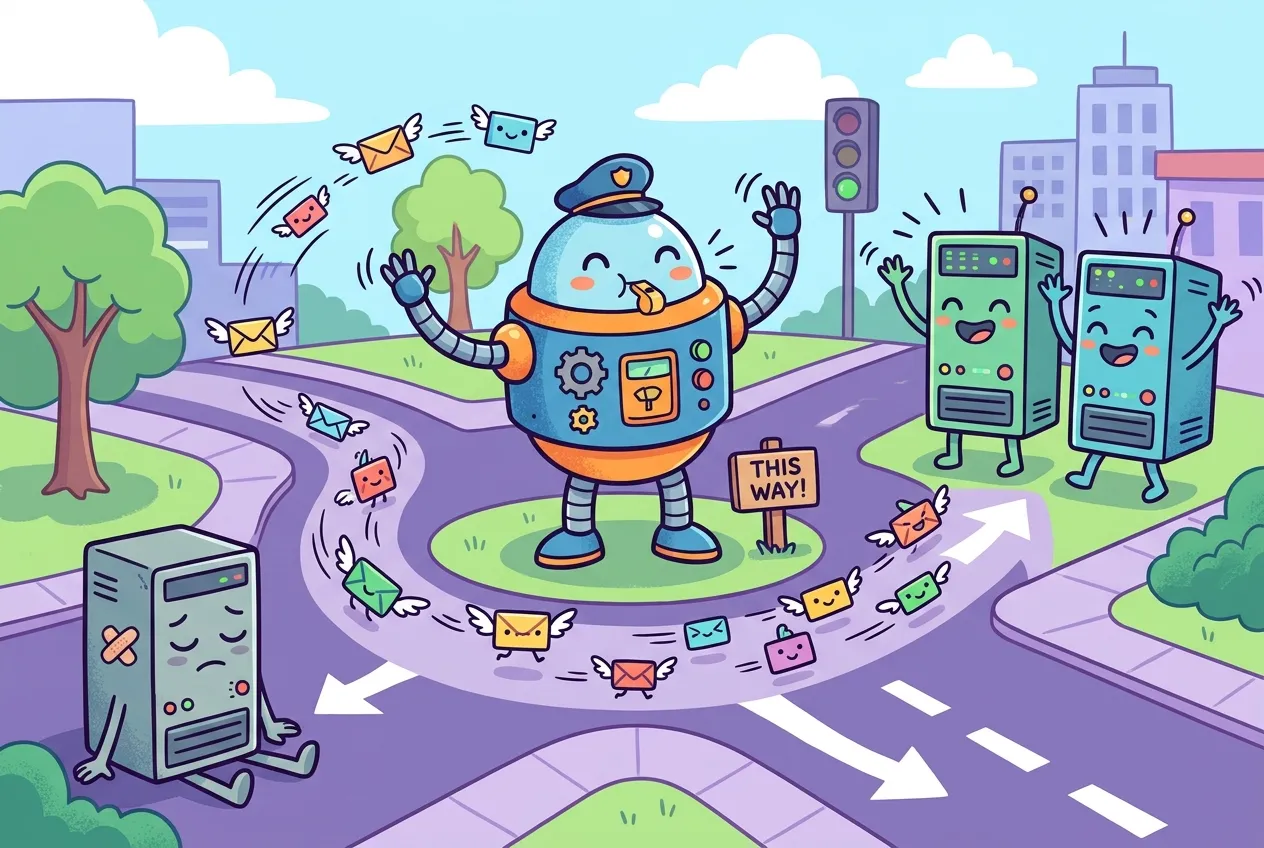
A popular website is never really one computer. Behind the single address you type sit a handful, or a few thousand, identical servers, and something has to decide which one answers each request. That traffic cop is the load balancer, and it is the reason a site can lose a server at 3 a.m. without anyone noticing.
This guide explains how load balancers work: where they sit, the difference between Layer 4 and Layer 7 balancing, the algorithms that pick a server, how health checks quietly remove broken machines, and the settings that trip up teams in production.
What a load balancer actually does
A load balancer accepts connections on behalf of a group of servers (often called a pool, upstream, backend or target group) and forwards each one to a member of that group. Clients only ever see the balancer's address. That simple indirection buys several things at once:
- Scale. Add servers to the pool and capacity grows without changing anything clients see.
- Availability. If a server fails its health checks, the balancer stops sending it traffic.
- Safe deployments. You can drain one server, update it and put it back while the others carry the load.
- A single front door. TLS certificates, request routing and security rules can live in one place.
Getting to the balancer itself usually starts with a DNS lookup that returns the balancer's address rather than any individual server's.
Layer 4 vs Layer 7: how load balancers work at each level
The "layer" refers to how much of the traffic the balancer reads before deciding where to send it.
Layer 4: transport-level balancing
A Layer 4 balancer looks only at connection details such as IP addresses, ports and protocol. It never parses the HTTP request, so it is fast and protocol-agnostic. AWS documents that its Network Load Balancer picks a target with a flow hash built from the protocol, source and destination IPs and ports, and the TCP sequence number, and then keeps each TCP connection on that one target for its whole life.
Layer 7: application-level balancing
A Layer 7 balancer terminates the connection, reads the HTTP request, and can route on the host name, path, headers or cookies. That lets it send /api to one pool and /images to another, add headers, and reuse backend connections. AWS's Application Load Balancer evaluates listener rules in priority order, adds X-Forwarded-For, X-Forwarded-Proto and X-Forwarded-Port headers so your app can see the real client, and can multiplex requests from many clients over one backend connection.
| Layer 4 (transport) | Layer 7 (application) | |
|---|---|---|
| Decides using | IPs, ports, protocol | Host, path, headers, cookies |
| Reads HTTP? | No | Yes, terminates and re-sends |
| Typical uses | Databases, game servers, raw TCP/UDP, very high throughput | Websites, APIs, microservice routing |
| TLS | Usually passed through or terminated without inspection | Terminated so the request can be inspected |
| Examples | AWS NLB, HAProxy mode tcp, NGINX stream | AWS ALB, HAProxy mode http, NGINX http |
The algorithms that choose a server
Cloudflare's learning center splits balancing algorithms into two families: static ones that ignore the servers' current state, and dynamic ones that look at it.
Static algorithms
- Round robin. Hand requests to each server in turn. It is NGINX's default and AWS ALB's default. It works best when servers are similar and requests cost about the same.
- Weighted round robin. Give bigger servers a larger share. In the NGINX docs, a server with
weight=5next to one with the default weight of 1 receives five of every six requests. - Hashing. Hash something about the request, such as the client IP or URL, so the same input always lands on the same server. HAProxy recommends
balance urifor cache servers, because each URL keeps hitting the cache that already holds it.
Dynamic algorithms
- Least connections. Send new work to the server with the fewest open connections. HAProxy's docs recommend it for long-lived sessions such as SQL, gRPC streams or LDAP, and caution that it fits short HTTP requests less well.
- Least outstanding requests / least time. Prefer the server with the fewest requests in flight or the fastest recent responses. AWS ALB offers
least_outstanding_requests; NGINX offersleast_time. - Power of two choices. Pick two servers at random and use the less busy one. It is cheap, avoids herding every balancer onto the same "least loaded" server, and HAProxy made
balance random(which uses two draws by default) its default algorithm starting with version 3.3.
upstream app_servers {
    least_conn;                          # dynamic: fewest active connections
    server app1.internal:8080 weight=2;  # twice the share of app2
    server app2.internal:8080 max_fails=3 fail_timeout=30s;
    server app3.internal:8080 backup;    # only used if the others are down
}

server {
    listen 80;
    location / {
        proxy_pass http://app_servers;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    }
}Health checks: how broken servers disappear
An algorithm is only useful if it chooses among servers that work. Balancers find out in two ways.
- Passive checks watch real traffic. In NGINX open source, if a server fails
max_failstimes withinfail_timeout, it is marked unavailable for a while. - Active checks probe each server on a schedule, typically by requesting a path like
/health. AWS ALB's defaults are an HTTP request to/every 30 seconds with a 5-second timeout, expecting a 200. A target needs 5 consecutive successes to be marked healthy and 2 failures to be marked unhealthy.
Make your health endpoint honest. It should check that the app can actually serve requests, but avoid making it fail just because one optional downstream service is slow, or a single hiccup can pull every server out at once.
Production details that bite
Sticky sessions
Some apps keep login state in server memory, so a user must keep returning to the same machine. Balancers support this with affinity cookies or IP hashing. AWS ALB stickiness is off by default and uses either a balancer-generated or an application cookie. It works, but it unbalances load and breaks when that server dies, so storing sessions in a shared database or cache is usually the better fix.
Draining and slow start
When you remove a server, in-flight requests need time to finish. AWS calls this the deregistration delay and sets it to 300 seconds by default. The reverse problem is a freshly started server getting a flood of traffic before its caches warm up; ALB's optional slow start ramps a new target's share up linearly over 30 to 900 seconds.
Long-lived connections
Round robin balances connections, not work. A server holding thousands of WebSocket connections may look idle by request count while it is actually the busiest box in the pool. Least connections is often the better choice there, and a per-client rate limit in front protects the whole pool from one noisy client.
Key takeaways
- A load balancer hides a pool of servers behind one address and spreads connections across them.
- Layer 4 balancers route on IPs and ports; Layer 7 balancers read HTTP and can route on paths, hosts and headers.
- Round robin is the common default; least connections and power-of-two-choices adapt to real load.
- Health checks, passive and active, are what make balancing improve availability.
- Plan for draining, slow start and long-lived connections before they surprise you.
Frequently asked questions
What is the difference between a load balancer and a reverse proxy?
A reverse proxy sits in front of servers and forwards requests to them. A load balancer is a reverse proxy, or a network device, whose main job is spreading traffic across several servers. Tools like NGINX and HAProxy do both.
Should I use a Layer 4 or Layer 7 load balancer?
Use Layer 7 for websites and APIs when you want routing by path or host, header handling and HTTP-aware health checks. Use Layer 4 for non-HTTP protocols or when you need raw throughput and minimal processing.
Which load balancing algorithm is best?
Round robin is fine when servers and requests are uniform. Choose least connections for long-lived connections, hashing when the same client or URL should hit the same server, and power of two choices for large, frequently changing pools.
Is the load balancer itself a single point of failure?
It can be. Managed cloud balancers run redundantly across availability zones, and self-hosted setups typically run two or more balancer nodes with a floating IP or DNS failover between them.
Sources
- NGINX documentation: HTTP load balancing
- HAProxy documentation: load balancing algorithms
- AWS documentation: How Elastic Load Balancing works
- AWS documentation: Health checks for Application Load Balancer target groups
- AWS documentation: Target groups for Application Load Balancers
- Cloudflare Learning Center: Types of load balancing algorithms
Comments
No comments yet — be the first to share your thoughts.
Join the discussion