How Vector Embeddings and Semantic Search Work: Cosine, HNSW and pgvector
How lists of numbers let software find meaning instead of matching keywords, and how to search millions of them fast
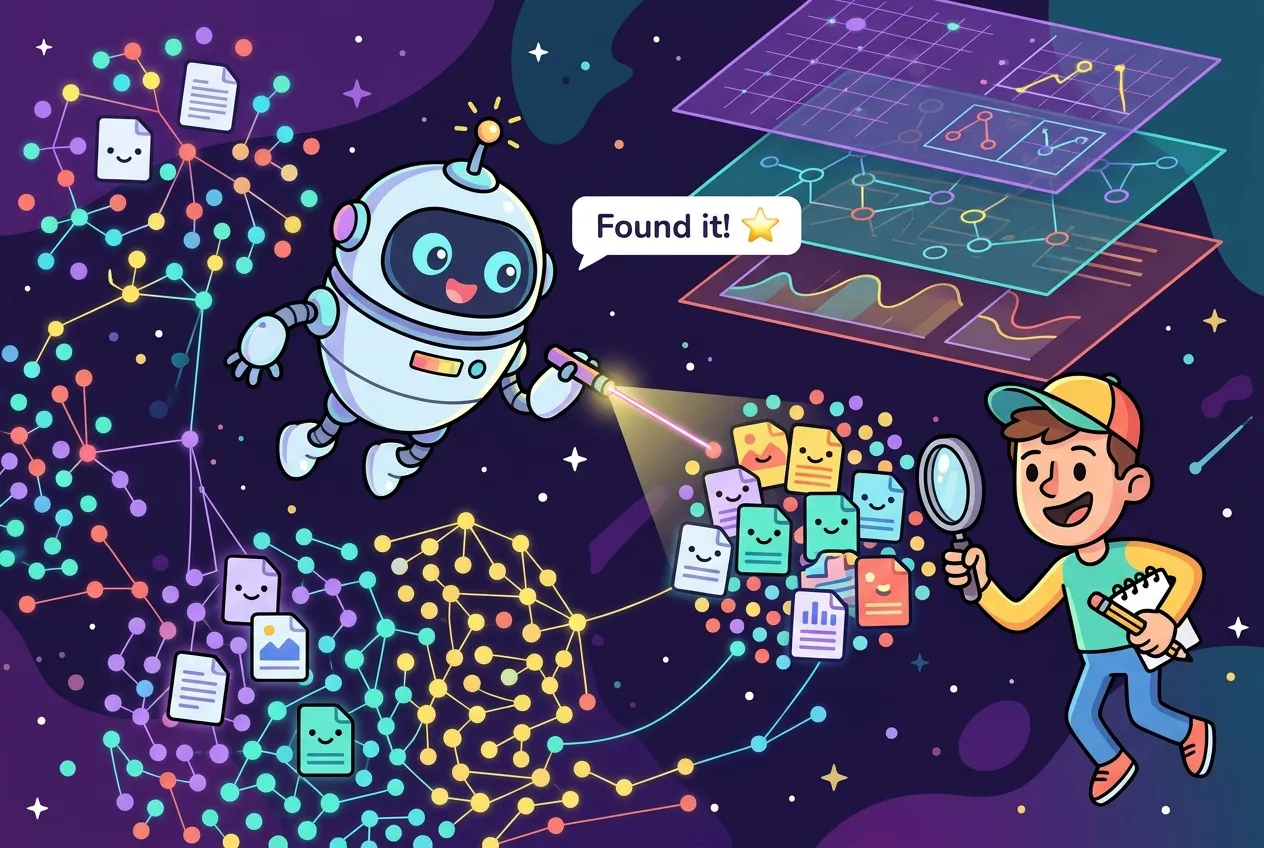
Type "my laptop won't turn on" into a modern help center and it finds the article titled "Troubleshooting power issues", even though the two share almost no words. That isn't keyword matching. It's math on lists of numbers called embeddings.
Embeddings sit underneath semantic search, recommendations, duplicate detection and the retrieval step that feeds documents to AI chatbots. This guide explains how vector embeddings and semantic search work: what an embedding actually is, how "closeness" gets measured, why searching millions of vectors needs special indexes like HNSW, and how to try it yourself in PostgreSQL.
What is a vector embedding?
An embedding is a way to turn something messy, like a sentence, a product or an image, into a fixed-length list of numbers. Google's Machine Learning Crash Course describes each item as a point in an n-dimensional embedding space, where similar items land near each other.
The course uses a food example that makes the idea click. Put every dish on a single "sandwichness" axis and hot dogs sit near shawarma. Add a second axis for "dessertness" and apple strudel moves away from the sandwiches. Add a third for "liquidness" and soups separate out. Each new dimension captures another way dishes can differ.
Real models do the same thing with far more dimensions, often hundreds or thousands, and they learn the axes from data rather than having a person name them. That's why individual dimensions are usually impossible to interpret, even though distances between points remain meaningful.
From word vectors to whole-passage embeddings
Early approaches such as word2vec gave every word a single fixed vector learned from which words appear in similar contexts. Google's course points out the weakness: one point per word can't represent words with several meanings. "Bank" the riverside and "bank" the lender get squashed into the same spot. Modern embedding models read whole passages, so the same word can contribute differently depending on its neighbours.
How semantic search uses embeddings
Once text becomes vectors, "find relevant documents" turns into "find the nearest points". A typical semantic search pipeline looks like this:
- Chunk your content into passages a few paragraphs long.
- Embed each chunk with an embedding model and store the vector next to the text.
- Embed the query with the same model when a user searches.
- Find the nearest vectors to the query vector.
- Return or rerank the matching chunks, or hand them to a language model as context.
The rule that matters most: queries and documents must be embedded with the same model. Vectors from different models live in different spaces, and comparing them is meaningless.
Measuring "close": cosine, dot product and Euclidean
There are a few common ways to score how near two vectors are:
| Measure | What it compares | pgvector operator |
|---|---|---|
| Cosine distance | The angle between vectors, ignoring their length | <=> |
| Inner (dot) product | Angle and length together | <#> (returns the negative) |
| Euclidean (L2) | Straight-line distance between points | <-> |
| L1 (taxicab) | Sum of per-dimension differences | <+> |
In practice the choice often matters less than people expect. OpenAI's embeddings FAQ notes that its vectors come normalized to length 1, which means cosine similarity can be computed as a plain dot product, and that cosine and Euclidean distance produce the same rankings. Check whether your model normalizes its output; if it does, pick whichever operator your database runs fastest.
Why you need approximate nearest neighbor search
The simplest way to find the nearest vectors is to compare the query against every stored vector. That's exact and, as the pgvector documentation notes, gives perfect recall. It's also a full scan, the same problem we covered in how database indexes work. With millions of vectors of a thousand dimensions each, comparing everything on every query gets slow.
A normal B-tree can't help, because there's no single sort order for points in high-dimensional space. Instead, vector databases use approximate nearest neighbor (ANN) indexes. They give up a small amount of accuracy, occasionally missing a true neighbour, in exchange for huge speed gains. The share of true neighbours an index actually returns is called recall.
How HNSW works
One of the most widely used ANN indexes is HNSW, short for Hierarchical Navigable Small World, introduced by researchers Malkov and Yashunin in a 2016 paper. The idea is a stack of graphs:
- Every vector is a node linked to some of its nearest neighbours.
- Each node is randomly assigned a top layer, with higher layers exponentially less likely, so upper layers are sparse and the bottom layer holds everything.
- Upper layers have long-range links for big jumps; lower layers have short links for fine detail.
- A search starts at the top, greedily hops toward the query, then drops a layer and repeats until it reaches the bottom.
If that sounds like a skip list, the authors make the same comparison. The layered design is what lets search cost grow roughly logarithmically with the size of the collection instead of linearly.
IVFFlat: the simpler alternative
The other common option, IVFFlat, splits vectors into clusters (lists) and only searches the few clusters closest to the query. It builds faster and uses less memory than HNSW, but pgvector's documentation says its speed-recall tradeoff is worse.
Try it: semantic search in PostgreSQL with pgvector
You don't need a dedicated vector database to start. The open-source pgvector extension adds a vector type and ANN indexes to PostgreSQL:
CREATE EXTENSION vector;

CREATE TABLE docs (
  id        bigserial PRIMARY KEY,
  content   text,
  embedding vector(1536)  -- match your model's dimensions
);

-- HNSW index for cosine distance (defaults shown)
CREATE INDEX ON docs
  USING hnsw (embedding vector_cosine_ops)
  WITH (m = 16, ef_construction = 64);

-- Find the 5 nearest chunks to a query embedding
SET hnsw.ef_search = 100;  -- default is 40; higher = better recall, slower
SELECT id, content
FROM docs
ORDER BY embedding <=> $1
LIMIT 5;The knobs are worth understanding. m sets how many links each node keeps per layer, ef_construction controls how hard the build searches for good neighbours, and ef_search sets how many candidates a query considers. Raising them buys recall at the cost of speed and memory.
Common pitfalls
- Mixing models. Re-embed everything when you switch embedding models; old and new vectors aren't comparable.
- Bad chunking. Chunks that are too long blur several topics into one vector; chunks that are too short lose context.
- Ignoring exact terms. Embeddings can miss product codes, names and error numbers. Many teams combine vector search with classic keyword search.
- Garbage in. Embeddings faithfully encode whatever you feed them, which is why high-quality data still matters more than model size.
- Privacy blind spots. Sending documents to a hosted embedding API shares their content. For sensitive data, consider running a model on your own hardware, the same trade-off behind local LLMs in the smart home.
Key takeaways
- An embedding turns text, images or items into a list of numbers where similar things sit close together.
- Semantic search embeds both documents and queries with the same model, then finds the nearest vectors.
- For normalized embeddings, cosine, dot product and Euclidean distance rank results the same way.
- Exact search scans everything; ANN indexes like HNSW and IVFFlat trade a little recall for big speed gains.
- PostgreSQL with pgvector is an easy way to add vector search to an existing app.
Frequently asked questions
What is the difference between semantic search and keyword search?
Keyword search matches the words you typed. Semantic search compares embeddings, so it can find passages with the same meaning even when they use different words.
Do I need a dedicated vector database?
Not always. Extensions like pgvector add vector types and ANN indexes to PostgreSQL, which is often enough for small and mid-sized collections. Dedicated vector databases add features for very large scale.
Which distance metric should I use?
Use the one your embedding model recommends. If its vectors are normalized to length 1, cosine, dot product and Euclidean distance give the same ranking, so choose the fastest.
What does recall mean for a vector index?
Recall is the share of the true nearest neighbours an approximate index actually returns. Exact search has perfect recall; tuning settings like ef_search trades speed for higher recall.


Comments
No comments yet — be the first to share your thoughts.
Join the discussion