How Virtual Memory Works: Pages, Page Tables, the TLB and Page Faults
The illusion that gives every program its own private memory, and the hardware that keeps it fast
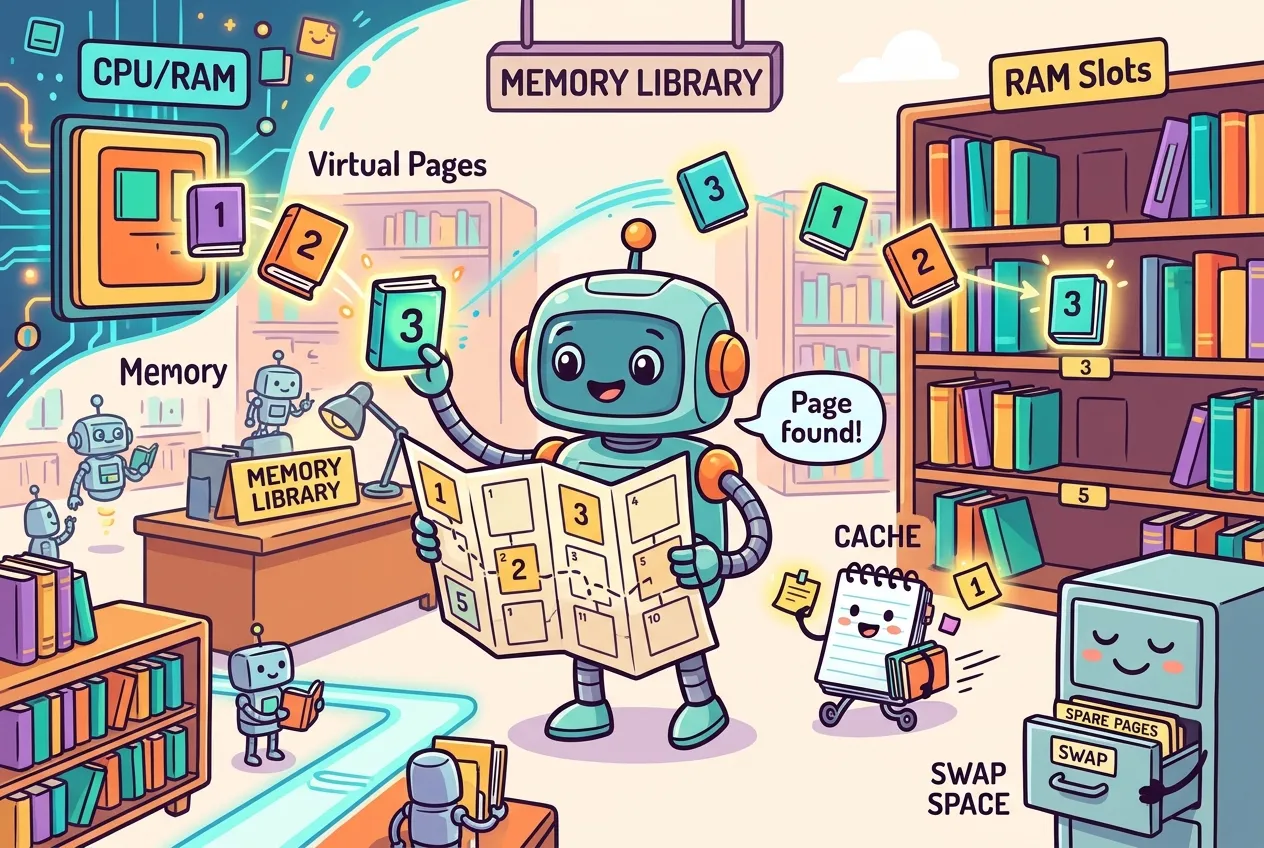
Every program on your computer believes it has a huge, private, tidy block of memory all to itself. None of them actually do. The illusion is called virtual memory, and it is one of the most important tricks in computing.
This guide explains how virtual memory works: what pages and page tables are, why the CPU needs a special cache called the TLB, what really happens during a page fault, and how huge pages and swapping fit in. You don't need to be a kernel developer to follow along.
Why computers fake their memory
In the early days, programs used physical addresses directly. That made life hard: two programs could overwrite each other, a buggy one could crash the whole machine, and every program had to fit into whatever RAM happened to be free.
Virtual memory fixes this by inserting a translation layer. Your program uses virtual addresses. Hardware called the Memory Management Unit (MMU) translates each one into a physical address in RAM on the fly. That single layer of indirection buys a lot:
- Isolation – each process gets its own address space, so one can't read or scribble on another's memory.
- Simplicity – programs see one large, contiguous range even when the RAM behind it is scattered.
- Protection – memory can be marked read-only or non-executable, and violations are caught by hardware.
- Efficiency – memory can be allocated lazily, shared between processes, or pushed out to disk when RAM runs short.
The idea is older than you might think. Paged virtual memory first appeared on the Ferranti Atlas in 1962, and it arrived on mainstream PCs with the Intel 80386 in 1985, the chip Linux 1.0 was written for.
Pages: memory in fixed-size chunks
Translating every single byte individually would be absurdly expensive. Instead, memory is divided into fixed-size blocks called pages (on the virtual side) and page frames (on the physical side). On x86-64, the standard page size is 4 KB.
With 4 KB pages, the lowest 12 bits of an address are the offset inside the page, since 212 is 4,096. Those bits pass through translation untouched. Only the upper bits, the virtual page number, get swapped for a physical frame number. Translate the page once, and every byte inside it comes along for free.
Page tables: the map from virtual to physical
The operating system keeps a page table for each process: a data structure that says which virtual page lives in which physical frame. Each entry also carries status bits, such as whether the page is present in RAM, whether it may be written, and a dirty bit that the hardware sets when the page is modified.
Why the table is a tree, not a list
A single flat table would be enormous. A 64-bit address space contains so many pages that a flat table would waste huge amounts of memory, almost all of it describing addresses the program never touches. So modern systems use a multi-level page table, a tree where empty regions can be marked unmapped high up and simply never get lower-level tables.
On x86-64 with 4-level paging, a 48-bit virtual address is split like this:
 47        39 38        30 29        21 20        12 11          0
+------------+------------+------------+------------+-------------+
|  Level 4   |  Level 3   |  Level 2   |  Level 1   |   Offset    |
|  9 bits    |  9 bits    |  9 bits    |  9 bits    |   12 bits   |
+------------+------------+------------+------------+-------------+
512 slots 512 slots 512 slots 512 slots byte in pageFour levels give 256 TiB of virtual address space. Newer Intel and AMD server chips support 5-level paging, which adds one more 9-bit level, stretches virtual addresses to 57 bits and raises the limit to 128 PiB. Linux added support in kernel 4.14. Because some software stores extra data in the upper bits of pointers, Linux still hands out addresses below the old 47-bit boundary unless a program explicitly asks for more.
Linux models all this in software as a five-level hierarchy named PGD, P4D, PUD, PMD and PTE. On hardware with fewer levels, the unused ones are "folded" away so the same code runs everywhere.
The TLB: a cache for translations
Here's the catch. Walking four levels of tables means four extra memory reads before the program can even fetch the byte it wanted. Doing that on every access would be ruinous.
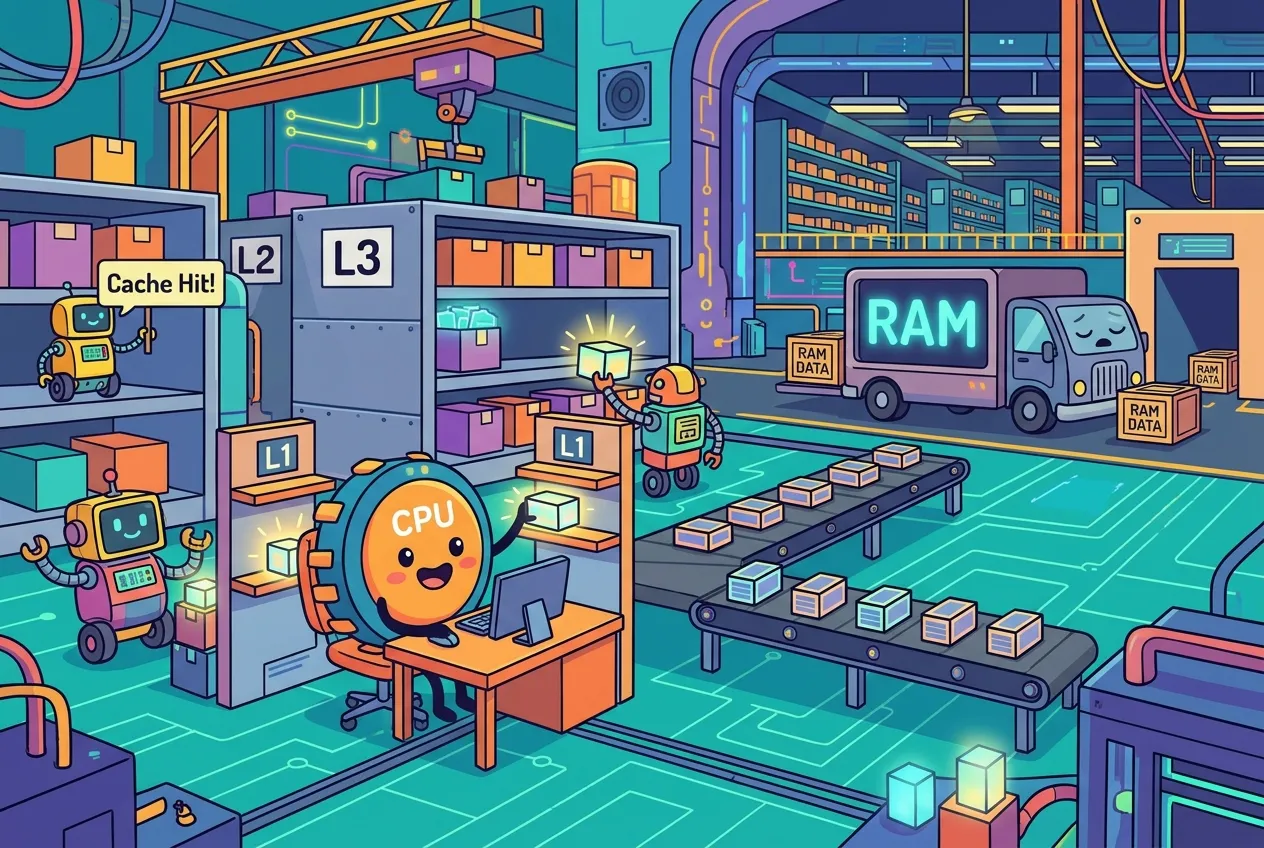
So the MMU keeps a small, very fast cache of recent translations called the Translation Lookaside Buffer (TLB), often backed by page-walk caches for the upper levels. On a TLB hit, translation is nearly free. On a miss, the hardware walks the page table, finds the entry and stores it in the TLB for next time.
The TLB is a close cousin of the data caches covered in our guide to how CPU caches work. The same rule applies: programs that touch memory in a compact, predictable pattern get far more hits.
Page faults: when translation fails
If the walk can't produce a usable translation, the MMU raises a page fault, an exception that pauses the program and hands control to the kernel. Despite the alarming name, most page faults are normal and expected. The table below shows how the common cases differ.
| Event | What happened | Who handles it | Typical cost |
|---|---|---|---|
| TLB miss | Translation not cached, but valid in the page table | Hardware page walk (on x86 and Arm) | A handful of memory reads |
| Minor fault | Page is valid but not mapped yet, e.g. first touch or copy-on-write | Kernel, no disk I/O | Microseconds |
| Major fault | Page must be read from disk (swap or a mapped file) | Kernel plus storage I/O | Much slower, bounded by the disk |
| Invalid access | Address not in the process's space, or a write to read-only memory | Kernel sends SIGSEGV | The program usually crashes |
Lazy allocation and copy-on-write
Two everyday tricks rely on page faults. With lazy allocation, asking for a large block of memory just reserves virtual addresses; physical frames are only handed out the first time each page is touched. With copy-on-write, a newly forked process shares its parent's pages read-only, and a private copy is made only when one of them writes. That's why starting a process is cheap, and it's the same sharing idea that lets Linux containers start in a blink.
Swapping and the OOM killer
When RAM runs short, the kernel can move rarely used pages out to a swap partition or file and mark them not present. Touching one later triggers a major fault and a trip to storage. The kernel docs are clear that swapping is a pressure-relief valve, not something you want happening constantly. If the kernel truly can't free enough memory, it invokes the out-of-memory (OOM) killer to terminate a process.
Huge pages: fewer, bigger translations
A TLB has a fixed number of entries, so with 4 KB pages it can only cover a small slice of a multi-gigabyte heap. Huge pages help by letting a higher-level entry map a large region directly. On x86-64 these are typically 2 MB (mapped at the PMD level) or 1 GB (at the PUD level). One 2 MB TLB entry covers 512 times as much memory as a 4 KB one.
Linux offers two flavors: static HugeTLB pages that an administrator reserves up front, and Transparent Huge Pages (THP), which the kernel assigns automatically. Databases and JVMs often benefit. The trade-offs are possible wasted memory and the work of finding large contiguous free regions, which is why some vendors recommend the madvise mode so only programs that ask get huge pages.
You can poke at all of this on a Linux box:
# Page size in bytes (usually 4096)
getconf PAGESIZE

# Does this CPU support 5-level paging?
grep -o -m1 la57 /proc/cpuinfo

# Current Transparent Huge Pages mode: [always], [madvise] or [never]
cat /sys/kernel/mm/transparent_hugepage/enabled

# Count minor and major page faults for a command
/usr/bin/time -v ls / 2>&1 | grep -i "page faults"Key takeaways
- Virtual memory gives every process its own private address space, translated to physical RAM by the MMU.
- Memory is managed in pages, 4 KB by default on x86-64; only the page number is translated, not the offset.
- Page tables are multi-level trees: 4 levels cover 256 TiB, and 5-level paging reaches 128 PiB.
- The TLB caches recent translations so most accesses skip the page-table walk entirely.
- Page faults are usually normal: they power lazy allocation, copy-on-write and swapping.
- Huge pages cut TLB pressure for memory-hungry apps, at the cost of some flexibility and possible waste.
Frequently asked questions
Is virtual memory the same as swap?
No. Virtual memory is the whole address-translation system, and it runs even on machines with no swap at all. Swap is just one optional feature built on top of it, letting the kernel park unused pages on disk.
Are page faults bad for performance?
Minor faults are cheap and happen constantly as programs start up and allocate memory. Major faults, which wait on disk, are the expensive kind. A steady stream of major faults usually means the system is short on RAM.
What causes a segmentation fault?
A segmentation fault happens when a program touches an address it isn't allowed to, such as a null or dangling pointer, or tries to write to read-only memory. The MMU raises a fault, the kernel finds no valid mapping, and it sends the SIGSEGV signal, which normally ends the process.
Should I turn on huge pages?
It depends on the workload. Large databases, JVMs and virtual machines with big, long-lived heaps often gain from them. For general desktop use the default settings are fine. Check your database or runtime vendor's guidance before changing THP system-wide.
Sources
- The Linux Kernel documentation: Page Tables
- Linux kernel mailing list: x86 5-level paging support patch
- The Linux Kernel documentation: Transparent Hugepage Support
- Oracle Linux documentation: Configuring Huge Pages
- Azul documentation: Enabling Huge Pages
- Wikipedia: Page table
- University of Illinois System Programming wiki: Introduction to Virtual Memory
Comments
No comments yet — be the first to share your thoughts.
Join the discussion