How CPU Caches Work: L1, L2, L3, Cache Lines and False Sharing
Why your processor spends so much time waiting, and how a few kilobytes of fast memory fix it
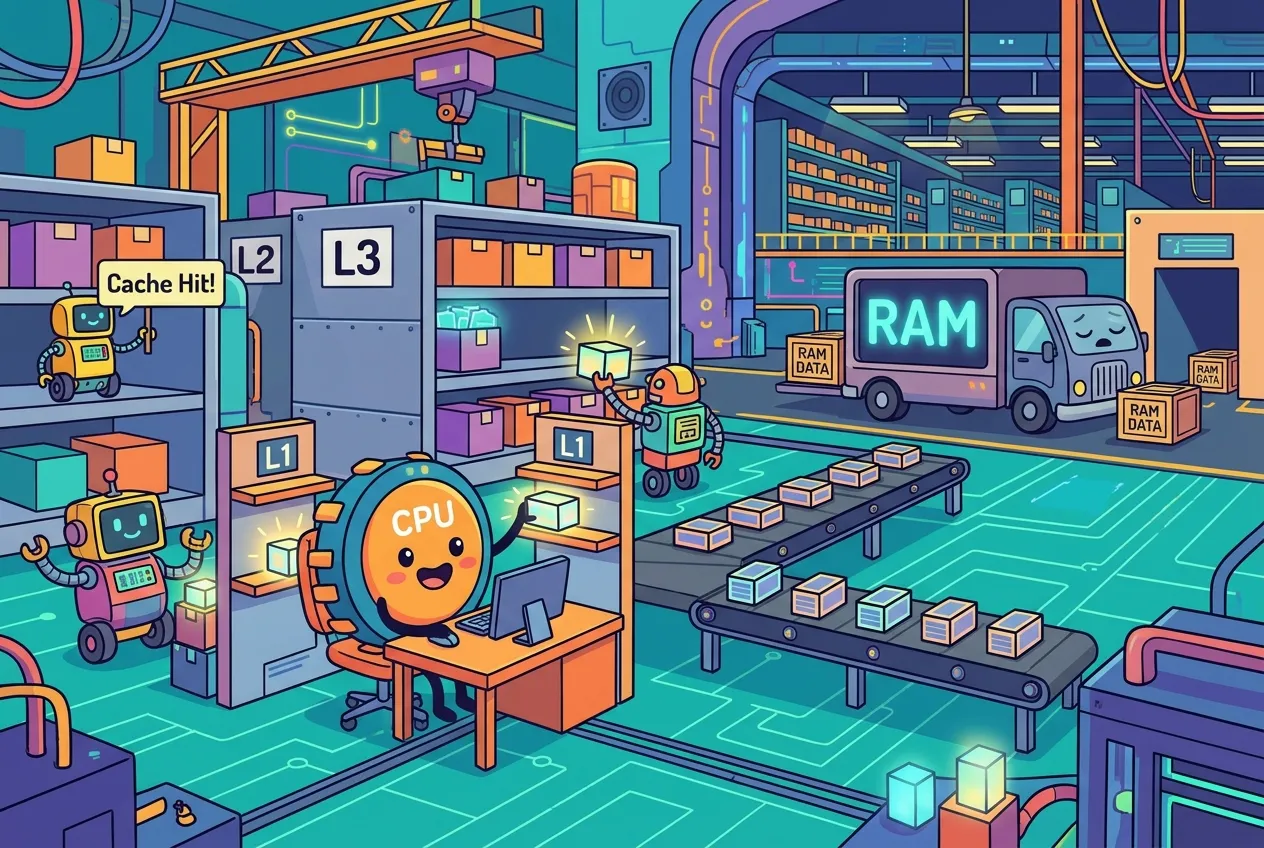
Your processor can do billions of things a second, yet it spends a surprising share of that time simply waiting for data. The fix is a stack of small, very fast memories sitting right next to the cores.
This guide explains how CPU caches work: why L1, L2 and L3 exist, what a cache line is, how the hardware decides where data goes, and why two loops that do the same math can run at wildly different speeds. No electrical engineering required.
Why CPUs need a cache at all
Main memory (DRAM) is large and cheap, but far away in processor terms. A typical trip to RAM costs on the order of 200 clock cycles, while the closest cache answers in about 4. During one memory stall, a core could have run hundreds of simple instructions if they didn't depend on the missing value.
Caches hide that gap by keeping copies of recently and frequently used data close to the core. They work because real programs are predictable in two ways, known together as locality of reference:
- Temporal locality – if you used a value recently, you'll probably use it again soon (a loop counter, a hot lookup table).
- Spatial locality – if you used one address, you'll probably use its neighbors next (walking through an array).
The CPU cache hierarchy: L1, L2 and L3
Instead of one big cache, modern chips use a ladder. Each step down is bigger, cheaper per bit and slower. On a typical desktop or server design, L1 and L2 belong to a single core, while L3 (the "last-level cache") is shared by all cores on the chip. L1 is usually split in two: one cache for instructions and one for data.
| Level | Typical size | Rough latency | Shared? |
|---|---|---|---|
| L1 (data + instruction) | 32–64 KB per core | ~4 cycles | Private to one core |
| L2 | 256 KB to a few MB per core | ~12 cycles | Usually private |
| L3 / last-level | 8 MB to well over 64 MB | ~40 cycles | Shared by all cores |
| DRAM | Gigabytes | ~200+ cycles | Whole system |
Treat those numbers as ballpark figures. Real latencies shift with clock speed, chip design, chiplet layout and how busy the other cores are. Some designs bend the pattern, too: Apple's M-series chips, for example, pair unusually large L1 caches with a big L2 shared by a cluster of cores.
When the core needs data it checks L1 first, then L2, then L3, and only then goes to DRAM. Each miss adds the cost of the next level down, which is why architects summarize performance with average memory access time: hit time plus miss rate multiplied by miss penalty. Shaving the miss rate a little can matter more than making hits faster.
Cache lines: the CPU never fetches just one byte
Caches don't move individual bytes. They move fixed-size blocks called cache lines. On x86-64 processors a line is 64 bytes, and most modern Arm cores use 64 too. Apple Silicon Macs report 128 bytes to software, and Go's runtime pads to 128 there to be safe.
Ask for one byte and the processor loads the whole aligned 64-byte block containing it. If you then read the next 63 bytes, they're already waiting. That's spatial locality paying off, and it's the main reason sequential access beats random access so dramatically.
How an address finds its line
The hardware splits each memory address into three parts:
- Offset – which byte inside the line. With 64-byte lines that's the lowest 6 bits.
- Index – which set of the cache the line must live in.
- Tag – the remaining high bits, stored alongside the line so the cache can confirm it holds the right address.
A direct-mapped cache gives each address exactly one possible slot, which is simple but causes collisions. A fully associative cache lets a line go anywhere, which is flexible but expensive to search. Real CPUs mostly use the middle ground, set-associative caches: an address maps to one set, and the line can sit in any of that set's several "ways." When a set is full, a replacement policy (usually an approximation of least-recently-used) picks a victim to evict.
Writes: write-back and dirty lines
Most modern caches are write-back: a store updates the cached copy and sets a "dirty" bit rather than going straight to RAM. The line is written down only when it's evicted, and then the whole line goes, even if you changed only four bytes of it. That saves a huge amount of memory traffic compared with writing every store through to RAM.
Cache-friendly code: a tale of two loops
Here's where caches stop being trivia. These two C functions add up the same 1,024 × 1,024 grid of integers. C stores 2D arrays row by row:
#define N 1024
int grid[N][N];

/* Fast: walks memory in order, uses all 16 ints in each 64-byte line */
long sum_rows(void) {
    long s = 0;
    for (int i = 0; i < N; i++)
        for (int j = 0; j < N; j++)
            s += grid[i][j];
    return s;
}

/* Slow: jumps 4,096 bytes per step, uses 1 int per line it loads */
long sum_cols(void) {
    long s = 0;
    for (int j = 0; j < N; j++)
        for (int i = 0; i < N; i++)
            s += grid[i][j];
    return s;
}The row loop consumes every integer in a line before moving on, and the hardware prefetcher spots the steady pattern and fetches ahead. The column loop touches one integer per line, then leaps 4 KB away, so it throws away 15 of every 16 integers it pulled in and often has to fetch them again later.
The same idea explains why database engines care so much about page layout, as covered in our guide to how B-tree database indexes work: whether it's a disk page or a cache line, fetching a block and using all of it wins.
A few habits follow from this:
- Prefer contiguous arrays over pointer-heavy structures like linked lists when you iterate a lot.
- Keep fields that are used together close in a struct, and move rarely used ones out of the hot path.
- Process data in blocks ("tiling") so each chunk fits in L1 or L2 before you move on.
- Measure before rewriting. Profilers with hardware counters show cache misses directly.
Multiple cores: coherence and false sharing
When several cores each keep private copies of memory, something must stop them from disagreeing. That job belongs to a cache coherence protocol. The classic one, MESI, tags every line with one of four states:
- Modified – only this cache has it, and it has been changed (dirty).
- Exclusive – only this cache has it, and it still matches memory.
- Shared – several caches may hold clean copies; none may write yet.
- Invalid – this copy is stale or absent.
A core may write only to a line it holds in Modified or Exclusive state. To write a Shared line, it first invalidates every other copy. Intel and AMD build on this with variants (MESIF and MOESI) that add states to cut memory traffic.
The fix is to keep independently written hot data on separate lines using padding or alignment. Intel's scaling guidance notes that padding to 128 bytes is sometimes needed because of adjacent-line prefetching. C++17 even offers a portable constant for this:
#include <atomic>
#include <new>

struct Counters {
    alignas(std::hardware_destructive_interference_size) std::atomic<long> hits;
    alignas(std::hardware_destructive_interference_size) std::atomic<long> misses;
};On Linux, perf c2c is a handy way to find cache lines that bounce between cores.
The same "keep a fast copy close, keep the copies consistent" trade-off shows up all over computing. It powers browsers and CDNs in our explainer on how HTTP caching works, and it continues below RAM in how SSDs work.
Key takeaways
- CPU caches exist because a trip to DRAM can take about 50 times longer than an L1 hit.
- L1 and L2 are usually private per core; L3 is a larger cache shared by all cores.
- Data moves in cache lines, 64 bytes on x86-64, so neighboring bytes come along for free.
- Sequential, compact data layouts use every byte of each line and let prefetchers help.
- Coherence protocols like MESI keep cores consistent, but cause false sharing when unrelated hot variables share a line.
- Pad or align independently written data onto separate lines, and confirm with a profiler.
Frequently asked questions
Is more L3 cache always faster?
No. A bigger L3 helps when your program's working set is larger than L2 but small enough to fit in L3, which is common in games and some databases. If your data already fits in smaller caches, or is far too large for any cache, extra L3 makes little difference.
Can I control the CPU cache from my code?
Not directly. The hardware decides what to keep. You influence it through data layout, access order and alignment, and occasionally through prefetch or non-temporal store instructions. In practice, layout and access order matter most.
How do I check my cache sizes?
On Linux, run lscpu. On macOS, sysctl -a | grep cache lists cache sizes and the reported line size. On Windows, Task Manager's Performance tab shows L1, L2 and L3 totals.
What is the difference between CPU cache and RAM?
Both hold data the CPU is using, but cache is fast SRAM built into the processor, measured in kilobytes to megabytes, while RAM is slower DRAM on separate modules measured in gigabytes. The cache holds copies of RAM contents, not separate data.
Sources
- TheoremPath: Cache Hierarchy (lines, associativity, write policy, AMAT)
- Deepak Gupta: What Is CPU Cache? L1, L2 and L3 Explained
- Cornell Virtual Workshop: Multicore Cache Sharing
- Intel Optimization Zone: Software scaling on large multi-core servers
- Wikipedia: MESI protocol
- cppreference: std::hardware_destructive_interference_size
- Go x/sys: cache line size fix for Apple M1
- Wikipedia: Apple M1 cache configuration
Comments
No comments yet — be the first to share your thoughts.
Join the discussion